Every Size Local AI In 24 Minutes
local-ailocal-llmhardwarememory-bandwidthraspberry-piapple-silicongpusimage-generation
Verdict: A model needs enough RAM to load and enough bandwidth to run fast; a 32 GB laptop runs every model category, home servers add size and uptime, and only an 8x H100 has plenty of both
TL;DR
- Tina Huang (Sept 2026) runs local AI on six classes of hardware, from a $20 ESP32 board to a rented 8x H100 server, and shows what each class can run: text, vision, speech, image, music and video models.
- Their main lesson is that capacity (RAM) decides whether a model fits, while bandwidth and the number of processors decide how fast it runs. A Raspberry Pi 5 and an iPhone 16 both have 8 GB, yet the iPhone runs models faster and can generate images because it has a wider memory bus plus a GPU and an NPU.
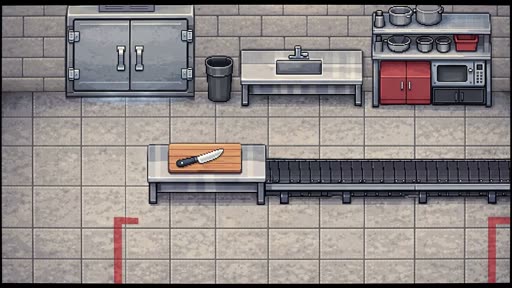
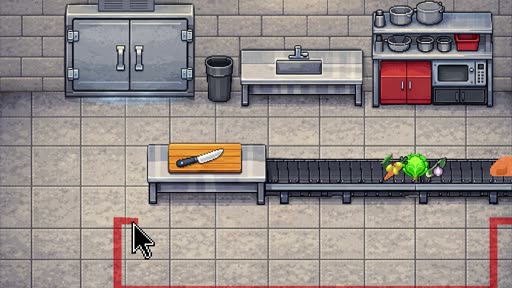
- They explain the parts with a restaurant kitchen: storage is the freezer, RAM the prep counter, the memory bus a conveyor belt, the CPU the head chef, the GPU a brigade of line cooks and the NPU single-purpose machines bolted to the wall.
- Their rule of thumb for laptops: take 75% of the RAM as usable and divide by 0.6 to get the largest model in billions of parameters, so their 32 GB MacBook Pro fits about 40B.
- The 128 GB AMD Ryzen AI Halo holds 70B to 120B models, many at once, but generates media slowly, and a rented RTX 4090 is the reverse, fast with only 24 GB. Only the 8x H100 (640 GB) has both, and Tina calls it aspirational.
Full summary
Six classes, one question
Tina sorts the hardware on their desk into memory classes and asks the same thing of each: which models fit, and how well they run. The classes are chips, mini computers, personal computers, home servers and GPUs. They rent the GPUs because they don't own a gaming PC. Each class ends with a summary slide that rates model categories (large language, coding, vision, speech-to-text, text-to-speech, image, music, video) by tier and fit, plus project ideas.
Chips: the ESP32 and the Arduino
Chips have no operating system, file system or separate memory; a model is flashed onto the board and either fits or doesn't. The Arduino Uno R4, with 32 KB of RAM, fits no models at all. The ESP32-S3, about $20 with a screen and two to five dollars without, has 8 MB and runs the TinyStories 260K and 3M models comfortably. They can only predict the next word to tell a short story, with no chat and no audio, image or video, but Tina suggests building on them: a "scrambled versus not scrambled" grammar game, or LEDs that show the story's mood. The Arduino comes back later. It has Wi-Fi, so it can display encouraging messages written by Qwen 3.6 35B running on their Mac Studio.
Mini computers: Raspberry Pi 5 and iPhone 16
Both have 8 GB, and both run an operating system that manages memory and lets several models run together. The Pi chains three models into a voice assistant: Whisper for speech-to-text, Qwen3 1.7B to answer, and Piper to speak. Asked what color an octopus is, it answers aloud. With a webcam, the Moondream vision model describes the room and Piper reads the description. The Pi runs micro and small language models easily, mid-size ones only at its limit, and small coding models barely. Image, music and video generation are out because it has no GPU, so they are painfully slow, though an image model would fit. Its strength is hardware add-ons, and Tina believes the Hugging Face robots run on a Pi.
The iPhone is different. iOS limits each app to about 4 to 5 GB, so mid-size 7B to 14B models that a Pi can just about load are off the table, and every model arrives through an app:
- Google's AI Edge Gallery for Gemma 4, a 1.5 GB vision model in the 1B to 4B range
- Draw Things for image generation, such as Stable Diffusion 1.5 at 2 GB
- Whisper Large for speech-to-text, plus any text-to-speech model
- Ultralytics for the YOLO11n detection model, the object-recognition technique behind face unlock and self-driving cars, which they say people rarely talk about
The kitchen lesson
To explain the difference they build a kitchen. Ingredients live in the freezer downstairs (storage) and are brought up to the prep counter (RAM). A conveyor belt (the memory bus) carries them to the head chef (CPU), who can make any dish but has one pair of hands, a brigade of less versatile line cooks (GPU), and machines bolted to the wall that each do one job fast on little power, like an onion chopper (NPU). Every answer from a model means running this whole kitchen.
The Pi and the iPhone have the same capacity but not the same bandwidth: most language models are limited by how fast the conveyor belt delivers weights, and the Pi's is narrow and slow. Unlike the Pi, the iPhone also has cooks and machines. Image, video and music generation need raw processing, which is why the CPU-only Pi can't do them however hard it works. Tina says the real picture is more complex (VRAM and unified memory are left out) and set a pop quiz.
Personal computers and the sizing rule
Tina's MacBook Pro has 32 GB, which they bought because it runs every category they test: language, coding, vision, image, video, text-to-speech, speech-to-text, audio, voice cloning and music. Their Hermes agent, which they use to run much of their life and work, runs Qwen3 models from 14B to 32B locally; Qwen3 Coder 30B works "pretty good" in the OpenCode harness; and their favorite image model is Flux Dev. They show separate slides for 8 GB and 16 GB laptops and give a rough rule for any other size:
- subtract 25% of the advertised RAM for everything else running
- divide what's left by 0.6 to get the largest model in billions of parameters
32 GB leaves 24 GB usable, and 24 divided by 0.6 is 40, so their laptop fits up to about 40B. Asking a chatbot works too, they add.
Home servers: Mac Studio and AMD Ryzen AI Halo
The entry point here would be a Mac mini, but they couldn't get one and bought a Mac Studio instead. Home servers make sense for two reasons: they stay on, so models keep running when a laptop is closed, and they usually have more capacity and bandwidth. Above this level, Tina says, no new categories open up; the gain is bigger models, better answers and more speed. The 64 GB Mac Studio runs language models of 27B to 32B, large coding, image and music models, and mid-tier video generation such as Wan 2.2, still very slowly.
The AMD Ryzen AI Halo advertises 128 GB, about 96 GB usable, enough for 70B models and frontier-class models of 100B to 250B. Llama 3.3 70B and GPT-OSS 120B both run fine, as does DeepSeek Coder V2. What Tina values most is keeping many models loaded at once, so a coding agent, a language model and image or video generation can work side by side. But its bandwidth is small, Tina warns, so it is slow, especially for image, video and music.
GPUs: rented RTX 4090 and 8x H100
Back in the kitchen, a discrete GPU is a bundle: more line cooks, each with a private prep counter and a very wide conveyor belt. None of the earlier devices can take an extra GPU, but a gaming PC can. They rent an RTX 4090, the high end of gaming GPUs. It generates images and video "really, really quickly". Large models don't fit in its 24 GB, but its bandwidth is far higher than the AMD box's.
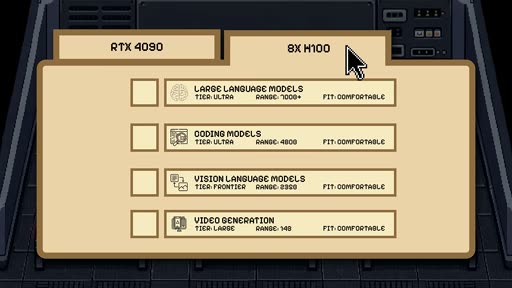
The final boss is a rented 8x H100 server with 640 GB, "massive capacity, and massive bandwidth." It runs ultra-tier language models of 700B and up, coding models of 480B and up, vision models and every kind of generation; a MiniMax video model produces minutes of video quickly. Tina calls it comparable to the frontier models sold through cloud APIs and describes everything below it as a choice between capacity and bandwidth. Short of being a model company or very rich, this is the most anyone can run, and they call it the aspirational class. They close with a quiz to help viewers retain what they learned.
Key moments
- [00:16] Chips — the Arduino Uno R4 (32 KB) fits nothing; the ESP32-S3 (8 MB) runs TinyStories. frame_0005.jpg
- [03:36] Pi voice assistant — Whisper, Qwen3 1.7B and Piper chained on a Raspberry Pi 5, plus Moondream describing a webcam frame. frame_0010.jpg
- [05:58] iPhone 16 — same 8 GB, about 4 to 5 GB per app; Gemma 4, Stable Diffusion 1.5, Whisper Large and YOLO11n through apps. frame_0012.jpg
- [07:47] The kitchen analogy — RAM as the prep counter, the memory bus as the conveyor belt, CPU, GPU and NPU as chef, cooks and machines. frame_0014.jpg
- [10:13] Why the Pi is slower — same capacity, narrower bus, and no GPU or NPU.
- [15:06] The sizing rule — 75% of RAM, divided by 0.6, gives the largest model in billions of parameters.
- [16:24] Why a home server — always on, with more capacity and bandwidth. frame_0028.jpg
- [18:29] AMD Ryzen AI Halo — 128 GB, about 96 usable; Llama 3.3 70B and GPT-OSS 120B run, media generation is slow. frame_0030.jpg
- [21:24] Rented RTX 4090 — fast image and video, but only 24 GB.
- [22:20] 8x H100 — 640 GB with both capacity and bandwidth; ultra-tier models and minutes of video. frame_0036.jpg
Hook microscope (0-10s)
-
Frames: 20 at 2 fps
Read these hook frames with the Read tool:
hook_frames/frame_0001.jpg(t=0.0s)hook_frames/frame_0002.jpg(t=0.5s)hook_frames/frame_0003.jpg(t=1.0s)hook_frames/frame_0004.jpg(t=1.5s)hook_frames/frame_0005.jpg(t=2.0s)hook_frames/frame_0006.jpg(t=2.5s)hook_frames/frame_0007.jpg(t=3.0s)hook_frames/frame_0008.jpg(t=3.5s)hook_frames/frame_0009.jpg(t=4.0s)hook_frames/frame_0010.jpg(t=4.5s)hook_frames/frame_0011.jpg(t=5.0s)hook_frames/frame_0012.jpg(t=5.5s)hook_frames/frame_0013.jpg(t=6.0s)hook_frames/frame_0014.jpg(t=6.5s)hook_frames/frame_0015.jpg(t=7.0s)hook_frames/frame_0016.jpg(t=7.5s)hook_frames/frame_0017.jpg(t=8.0s)hook_frames/frame_0018.jpg(t=8.5s)hook_frames/frame_0019.jpg(t=9.0s)hook_frames/frame_0020.jpg(t=9.5s)
-
Word-level transcript (41 words):
  [  0.12s] Hello!
  [  1.05s] Today
  [  1.19s] we're
  [  1.37s] going
  [  1.56s] to
  [  1.63s] be
  [  1.70s] running
  [  2.00s] every
  [  2.57s] size
  [  2.81s] AI
  [  3.00s] locally
  [  3.50s] with
  [  3.78s] the
  [  4.09s] hardware
  [  4.56s] that
  [  4.79s] we
  [  4.91s] have
  [  5.16s] here
  [  5.32s] and
  [  5.46s] see
  [  5.60s] what
  [  5.79s] we
  [  5.94s] can
  [  6.02s] do
  [  6.18s] with
  [  6.37s] it.
  [  6.56s] Hopefully
  [  7.03s] give
  [  7.24s] you
  [  7.46s] guys
  [  7.60s] some
  [  7.89s] ideas
  [  8.07s] for
  [  8.22s] cool
  [  8.43s] things
  [  8.75s] that
  [  9.03s] you
  [  9.10s] can
  [  9.41s] build
  [  9.51s] with
  [  9.80s] local
- 0.0-3.0s: Medium shot at their desk in front of a bookshelf, holding up a small board in each hand: "Hello. Today we're going to be running every size AI locally".
- 3.5-6.0s: Cut to the whole lineup on a white table as they say "with the hardware that we have here": MacBook Pro, AMD box, Mac Studio, Raspberry Pi, ESP32, Arduino and iPhone, with Tina looking over them.
- 6.5-10.0s: Back to the desk shot, both hands counting off on their fingers: "Hopefully give you guys some ideas for cool things that you can build with local AI".
Pattern: a scope promise ("every size") backed in under four seconds by a shot of all the hardware, then a builder's payoff (ideas to build). The lineup shot is the hook: the viewer sees the whole range before any explanation.
Editorial profile
- Shots: 40
- Cuts/min: 1.64
- Mean shot length: 36.56s
- Median shot length: 36.69s
- Talking-head ratio: n/a (opencv not installed)
Talking head at a home desk, cut with phone-shot demo clips, pixel-art explainer scenes (a kitchen, classrooms, a "Select Class" game menu) and game-style summary cards; quizzes and summary slides make it work like a course module. Pacing numbers come from uniform sampling (the detector found no cuts), so they don't measure the edit.
Quotable moments
- [02:44] "It is not capable of holding a conversation like a chat."
- [10:26] "These two devices have the same amount of RAM, which means that the same amount of capacity, but they do not have the same amount of bandwidth"
- [17:46] "It's not about unlocking new categories of AI models at this point. It's just about being able to run a bigger models"
- [21:58] "The downside of this GPU is that it only has 24 gigs of memory."
- [23:36] "Everything up to this GPU is kind of just forcing you to choose between like capacity and bandwidth"
Entities mentioned
- People: tina-huang
- Companies: Apple, Google, AMD, Nvidia, Hugging Face, Ultralytics, Alibaba (Qwen), Meta (Llama), OpenAI (GPT-OSS), DeepSeek, MiniMax
- Tools / products: Arduino Uno R4, ESP32-S3, Raspberry Pi 5, iPhone 16, MacBook Pro, Mac Studio, Mac mini, AMD Ryzen AI Halo, RTX 4090, H100, TinyStories, Whisper, Qwen3, Qwen3 Coder, Qwen 3.6, Piper, Moondream, Gemma 4, AI Edge Gallery, Draw Things, Stable Diffusion 1.5, YOLO11n, Hermes agent, OpenCode, Flux Dev, Wan 2.2, Llama 3.3 70B, GPT-OSS 120B, DeepSeek Coder V2
Concepts surfaced
- capacity-vs-bandwidth: a model has to fit in RAM, and its speed then depends on memory bandwidth and processors. Below the 8x H100 class, every device trades one for the other.
- memory-bandwidth-bound-generation: language models are limited by how fast weights reach the processors, which is why an iPhone beats a Raspberry Pi with the same 8 GB.
- ram-to-parameters-rule: usable RAM is about 75% of the advertised figure; divide by 0.6 for the largest model in billions of parameters.
- Kitchen analogy for AI hardware: storage, RAM, memory bus, CPU, GPU and NPU as freezer, prep counter, conveyor belt, head chef, line cooks and bolted machines.
- Media generation needs compute: image, music and video models need GPUs, so a CPU-only board can't run them in practice even when they fit.
Frame timeline
What's said while each frame is on screen.
[00:00]
Hello. Today we're going to be running every size AI locally with [music] the hardware that we have here and see what we can do with it. Hopefully give you guys some ideas for cool things that you can build with local AI, too. Let's go. A portion of this video is sponsored by Crusoe. So, I'm going to be grouping the hardware that I have here into different classes, different memory classes. So, the first class are chips. So, chips, as they are called, are literally just...
[00:54]
on screen, which is big enough to fit, drumroll, please, no models. That's right, nothing fits on here. Alas. >> [laughter] >> I actually just got this Arduino Uno R4 as part of a set cuz I'm trying to learn hardware and it unfortunately does not fit any AI models, but do not be fooled. That does not mean I cannot use this with local AI. I actually can since it has a Wi-Fi functionality, so I can connect with some of my bigger devices. But first, let's actually...
[01:31]
I got this for around $20 USD. Although this one does come with a screen, so if you get it without the screen, you're looking at like two to five dollars, so cheap. And you can actually run AI models on here, two AI models, actually. Both of them are called Tiny Stories models, which, as its name suggests, allows you to run Tiny Stories. Let me show you what it looks like. So, this one is the Tiny Stories 1 megabyte model and then here is the Tiny Stories 3 megabyte model....
[02:51]
any multimodality models like audio, music, video, or images. For that, we're going to need to move on to the next class of devices, which is the mini computers category. This is a Raspberry Pi, the Pi 5, and this is my personal iPhone 16. Now, these are proper computing devices. They run an operating system. The Raspberry Pi runs a Linux, and my iPhone runs the iOS. And they're able to do things like manage memory, file systems, and run multiple programs. And so you can...
[03:57]
can be blue, green, red, or even white, depending on the species. >> First is using a speech-to-text AI model called Whisper in order to listen to it. Then I have the Quiet and Three 1.7B model. It's a large language model, which is an LLM, to be able to interpret it and then come out with a response. And then the Piper model, which is a tiny text-to-speech model, is able to actually answer it out loud on the speakers. Isn't that crazy? I'm able to have full...
[04:36]
describe it. And the tiny text-to-speech model Piper is able to describe what it sees. >> Here is the camera, the webcam, attached to the Raspberry Pi. >> The image features a woman sitting in a chair looking at her cell phone. She is wearing a black shirt and is surrounded by a variety of books and other items. There are at least 13 books scattered around the room, some of which are placed on a bookshelf. A backpack can be seen near the woman. A potted plant is...
[05:51]
accessories and sensors to your Raspberry Pi. In fact, I believe the Hugging Face robots are running off a Raspberry Pi as well. So, yes, I'm going to put on a summary slide now, including some ideas of things that you can build with a Raspberry Pi. And please do check out the free guide linked below for a quick start guide. Now, let's talk about the iPhone 16, which also has 8 gigs of RAM, [music] same as the Raspberry Pi, but it is so different. For one, because it is...
[07:34]
all things from facial recognition on your devices to self-driving cars, cuz you know, you got to be able to recognize different objects as we're driving. We don't really talk about this class of models very much, these detection models, but they're actually very, very useful. Isn't that really cool? I'm going to put on screen now a summary slide including some ideas of things that you can build using your phone with local AI. A small lesson on AI hardware. Now, think about...
[08:50]
chefs, cooks, and machines to process them into hopefully a meal. So, say for example, we want to prepare a salad. Well, first got to go get all of the salad stuff from a deep storage in the freezer and put them onto prep counter like your carrots, lettuce, olives, [music] chicken, other salad stuff. Then we put on the conveyor belt and it gets passed through and the head chef starts giving out orders. Tells all the line cooks to be chopping up all the vegetables and also...
[09:21]
everything comes together and voila, we get a salad. Yay! Amazing. So, this is a great analogy for how AI models work on our devices. So, this time what we want to be cooking is a model. So, we walk down to our freezer downstairs except we call it storage and we grab our model and we put it onto our prep counter which we call the RAM. Then we pass it along the conveyor belt which we call a memory bus, and hand it to our head chef, call it the CPU, who then also directs the...
[10:34]
the same amount of capacity, but they do not have the same amount of bandwidth, which is referring to the conveyor belt between the prep counter [music] and our cook and our chefs. You see, for most large language models, they're bottlenecked by how quickly you can deliver them from the RAM, the prep counter, to the chefs and the cooks to and the machines to process the model and get them to be running. On a Raspberry Pi, this conveyor belt, the memory bus, is quite narrow...
[11:49]
for now, amazing. You now have an understanding of AI hardware. Yay! I'll put on screen now a little pop quiz. Answer these questions and put them into the comments to make sure that you're paying attention. Of course, what I said about AI hardware is much more simplified than it actually is. There's concepts like VRAM, unified memory, like so much more, which I'm not going to go into too much more detail about in this video, cuz I'm sure this video is already very long....
[12:26]
themselves. For that, Crusoe Intelligence Foundry has been amazing. It primarily gives you two things: serverless inference to run open models without touching any of the underlying GPU infra. And serverless fine-tuning to customize the open models on your own data without having to own or manage any hardware. You can fine-tune a model, deploy it in one click, and start calling it with an API in minutes. Seriously, the first time that I did this, I almost shed a tear. There...
[13:37]
the reason why I got a MacBook Pro with 32 gigs of RAM is because this is the machine that pretty much allows me to run any category of AI models. I can run large language models, coding models, visual language models for visual analysis, image generation, video generation, text-to-speech, speech-to-text, audio generation, voice cloning, and music generation. >> All of this I can run locally. And not only can I run each of these models locally by itself, I'm also able...
[14:59]
have 8 gigs of RAM and 16 gigs of RAM. These are the general RAM sizes of laptops that most people have. But, if you do have something that's not like 8 gigs or 16 gigs, literally you have something smaller, bigger, something in the middle, that is okay as well. Because I'm also teach you a formula for calculating roughly the size of model that you can run on your machine giving the amount of RAM that you have. Okay, ready? The equation is that take the total amount of RAM...
[15:43]
- So my MacBook Pro can fit a model of up to 40 billion parameters. That is a very rough way of figuring it out. Of course, you can also just ask one of your favorite AI chatbots. Hey, this is what kind of models can I fit on it? You know, that works too. But in any case, I hope that is helpful. I want to now move on to the next category of devices, home servers. The two that I have to demo right now is the Mac Studio and the AMD Ryzen AI Halo. All right, the Mac Studio...
[16:38]
stuff like that. And when you close it, your, you know, your model stop working in case you were doing something with it. But the home servers, these machines are always-on. They are designed to be always-on. So they don't close down. You can constantly doing stuff and running your AI models 24/7. That's the first attractive part. And the second reason is that generally these home server devices do have more capacity and bandwidth. So it can run a bigger models and do it...
[18:30]
with a Mac Studio, as well as some ideas for things we can build. And let's move on to the AMD Halo, which is 128 GB of advertised RAM. Now, with 128 GB of advertised RAM, around 96 GB of usable RAM, it is now able to comfortably run extra large models in the 70B range and frontier models in the 100 to 250B range. We can see that Llama 3.3 70B is able to run fine, and GPT-OSS 120B is also able to run fine. It's also able to run extra large tier of coding models, like the...
[19:46]
First, let me explain GPUs a little bit more. Remember that analogy that we had earlier, the restaurant kitchen analogy? We said that a GPU is like having a brigade of line cooks. Because we have so many of them, they're able to work really, really quickly and they do compute very fast. Now, this matters the most when it comes to music generation, image generation, and video generation. Cuz to be able to produce these, you just need like a lot of processing power. So, you...
[20:16]
why they can do things like music generation, image generation, and video generation, but they do it really, really slowly cuz they're not specialized at doing this. But, the good news is that there is a way to be really good at processing and be able to do really fast and really good image, music, and video generation. And that is by getting more discrete GPUs. You see, a GPU actually isn't just line cooks. It's actually a bundle. When you get another GPU, you get cooks,...
[21:37]
RTX 4090. This is a pretty high-end GPU that you might have in a high-end gaming set. Let's do this quickly, because it's costing me by the hour. We're going to log in here, and then I'm going to run an image generation model. You can see that it is really, really quickly. And here is a video generation as well. Really, really quick. Now, the downside of this GPU is that it only has 24 gigs of memory. So, you can think about it almost like the opposite of the AMD device,...
[22:44]
one, because it's [music] costing me so much money every minute. But, for you guys, it's worth it. On here, not only can we run ultra-large tier large language models up to 700 billion parameter-plus ultra-large coding models, 480 billion parameter-plus visual language processing as well, and all types of multi-modal generation. Specifically, let's check out video generation. Using the Minimax H3 model, we can see that it's able to generate minutes of video, and it does...
[23:23]
>> This is pretty much what you can run assuming that you're not like a literal model development company or just have like a lot of money. But, it really is comparable at this point to the frontier models that you're paying for through cloud APIs. You see everything up to this GPU is kind of just forcing you to choose between like capacity and bandwidth, right? Like the AMD Halo is all about big capacity but low bandwidth, and the RTX 4090 is all about small capacity...
[24:18]
below to help you retain all of the information that we have covered today. Thank you so much, and I will see you guys in the next video or live stream.
Transcript
Source: captions.
[00:02] Hello. Today we're going to be running every size AI locally with [music] the
[00:04] every size AI locally with [music] the hardware that we have here and see what
[00:06] hardware that we have here and see what we can do with it. Hopefully give you
[00:07] we can do with it. Hopefully give you guys some ideas for cool things that you
[00:09] guys some ideas for cool things that you can build with local AI, too. Let's go.
[00:11] can build with local AI, too. Let's go. A portion of this video is sponsored by
[00:13] A portion of this video is sponsored by Crusoe.
[00:18] So, I'm going to be grouping the hardware that I have here into different
[00:20] hardware that I have here into different classes, different memory classes. So,
[00:22] classes, different memory classes. So, the first class are chips. So, chips, as
[00:25] the first class are chips. So, chips, as they are called, are literally just
[00:27] they are called, are literally just chips, just computer chips. They have no
[00:29] chips, just computer chips. They have no operating system, no file system, and no
[00:31] operating system, no file system, and no separate memory stick, either. Literally
[00:33] separate memory stick, either. Literally everything is just built into these
[00:35] everything is just built into these boards. So, when we try to run an AI
[00:36] boards. So, when we try to run an AI model on these, we're not even
[00:38] model on these, we're not even installing it. We just literally stick
[00:40] installing it. We just literally stick it on here and if it fits, it sits and
[00:42] it on here and if it fits, it sits and we can run it, or not. And in my case,
[00:43] we can run it, or not. And in my case, the smallest one that I have here is an
[00:45] the smallest one that I have here is an Arduino R4 Uno. It has only 32 kilobytes
[00:48] Arduino R4 Uno. It has only 32 kilobytes of RAM. I will put the rest of the stats
[00:50] of RAM. I will put the rest of the stats on screen, which is big enough to fit,
[00:52] on screen, which is big enough to fit, drumroll, please, no models. That's
[00:55] drumroll, please, no models. That's right, nothing fits on here. Alas.
[00:57] right, nothing fits on here. Alas. >> [laughter]
[00:58] >> [laughter] >> I actually just got this Arduino Uno R4
[01:00] >> I actually just got this Arduino Uno R4 as part of a set cuz I'm trying to learn
[01:02] as part of a set cuz I'm trying to learn hardware and it unfortunately does not
[01:03] hardware and it unfortunately does not fit any AI models, but do not be fooled.
[01:06] fit any AI models, but do not be fooled. That does not mean I cannot use this
[01:08] That does not mean I cannot use this with local AI. I actually can since it
[01:10] with local AI. I actually can since it has a Wi-Fi functionality, so I can
[01:11] has a Wi-Fi functionality, so I can connect with some of my bigger devices.
[01:13] connect with some of my bigger devices. But first, let's actually talk about
[01:14] But first, let's actually talk about something that can actually fit an AI
[01:16] something that can actually fit an AI model. Isn't this shocking? It is so
[01:19] model. Isn't this shocking? It is so tiny. This is the ESP32-S3
[01:22] tiny. This is the ESP32-S3 and it has 8 megabytes of RAM. I will
[01:25] and it has 8 megabytes of RAM. I will put the rest of the stats on screen and
[01:26] put the rest of the stats on screen and I got this for around $20 USD. Although
[01:28] I got this for around $20 USD. Although this one does come with a screen, so if
[01:30] this one does come with a screen, so if you get it without the screen, you're
[01:31] you get it without the screen, you're looking at like two to five dollars, so
[01:34] looking at like two to five dollars, so cheap. And you can actually run AI
[01:35] cheap. And you can actually run AI models on here, two AI models, actually.
[01:38] models on here, two AI models, actually. Both of them are called Tiny Stories
[01:39] Both of them are called Tiny Stories models, which, as its name suggests,
[01:41] models, which, as its name suggests, allows you to run Tiny Stories. Let me
[01:43] allows you to run Tiny Stories. Let me show you what it looks like. So, this
[01:44] show you what it looks like. So, this one is the Tiny Stories 1 megabyte model
[01:47] one is the Tiny Stories 1 megabyte model and then here is the Tiny Stories 3
[01:50] and then here is the Tiny Stories 3 megabyte model. You can run both of
[01:52] megabyte model. You can run both of these very comfortably. So, yes, I can
[01:54] these very comfortably. So, yes, I can run the Tiny Stories 260K model and the
[01:56] run the Tiny Stories 260K model and the Tiny Stories 3M model very comfortably.
[01:58] Tiny Stories 3M model very comfortably. And honestly, this is just a start
[02:00] And honestly, this is just a start getting a model running. You can make it
[02:02] getting a model running. You can make it so much cooler by adding on different
[02:04] so much cooler by adding on different modules to it. For example, you can make
[02:05] modules to it. For example, you can make it into a little game called scrambled
[02:07] it into a little game called scrambled versus not scrambled. Might be useful if
[02:09] versus not scrambled. Might be useful if you're learning English grammar. And you
[02:11] you're learning English grammar. And you can attach LED lights that represent the
[02:12] can attach LED lights that represent the mood of the story that's being produced.
[02:14] mood of the story that's being produced. So many cool things that you can do.
[02:16] So many cool things that you can do. Maybe I will make another video
[02:17] Maybe I will make another video showcasing stuff that you can build
[02:19] showcasing stuff that you can build using these little devices. But alas, we
[02:21] using these little devices. But alas, we do not have time in this video. So here
[02:23] do not have time in this video. So here is a summary slide for the models that
[02:25] is a summary slide for the models that we can run on the ESP32 and some ideas
[02:27] we can run on the ESP32 and some ideas for AI projects that you can build. Take
[02:28] for AI projects that you can build. Take a screenshot. In the free guide in the
[02:30] a screenshot. In the free guide in the description, I will also link a little
[02:31] description, I will also link a little quick start guide for how to get started
[02:33] quick start guide for how to get started building. So these tiny stories models
[02:35] building. So these tiny stories models are only able to do the very basics of
[02:37] are only able to do the very basics of predicting the next word in order to
[02:38] predicting the next word in order to form a coherent story, which is still
[02:40] form a coherent story, which is still very impressive actually given how small
[02:42] very impressive actually given how small it is. And you can build some really
[02:43] it is. And you can build some really cool things on top of that, too. But it
[02:45] cool things on top of that, too. But it is not capable of holding a conversation
[02:47] is not capable of holding a conversation like a chat. And it's not able to run
[02:48] like a chat. And it's not able to run any multimodality models like audio,
[02:50] any multimodality models like audio, music, video, or images. For that, we're
[02:52] music, video, or images. For that, we're going to need to move on to the next
[02:54] going to need to move on to the next class of devices, which is the mini
[02:56] class of devices, which is the mini computers category.
[03:04] This is a Raspberry Pi, the Pi 5, and this is my personal iPhone 16. Now,
[03:06] this is my personal iPhone 16. Now, these are proper computing devices. They
[03:09] these are proper computing devices. They run an operating system. The Raspberry
[03:10] run an operating system. The Raspberry Pi runs a Linux, and my iPhone runs the
[03:13] Pi runs a Linux, and my iPhone runs the iOS. And they're able to do things like
[03:14] iOS. And they're able to do things like manage memory, file systems, and run
[03:16] manage memory, file systems, and run multiple programs. And so you can
[03:18] multiple programs. And so you can actually have multiple models as long as
[03:19] actually have multiple models as long as they fit into these devices. But what is
[03:21] they fit into these devices. But what is really interesting is that both of these
[03:23] really interesting is that both of these actually have 8 gigs of RAM. Yet, they
[03:26] actually have 8 gigs of RAM. Yet, they are not able to run the same kinds of
[03:28] are not able to run the same kinds of models. I'm going to give you guys a
[03:29] models. I'm going to give you guys a quick lesson on AI hardware in just a
[03:31] quick lesson on AI hardware in just a little bit. But first, I want to show
[03:33] little bit. But first, I want to show you what these guys can do. This is the
[03:34] you what these guys can do. This is the Raspberry Pi, the Pi 5. And even though
[03:37] Raspberry Pi, the Pi 5. And even though it looks very small, it is very mighty
[03:39] it looks very small, it is very mighty because it is a full-blown mini
[03:41] because it is a full-blown mini computer. Let me show you what you can
[03:42] computer. Let me show you what you can do with it.
[03:44] do with it. What color is an octopus?
[03:46] What color is an octopus? >> Octopuses come in a variety of colors,
[03:49] >> Octopuses come in a variety of colors, but they are usually camouflage,
[03:51] but they are usually camouflage, blending with their surroundings. They
[03:52] blending with their surroundings. They can be blue, green, red, or even white,
[03:55] can be blue, green, red, or even white, depending on the species.
[03:58] depending on the species. >> First is using a speech-to-text AI model
[04:00] >> First is using a speech-to-text AI model called Whisper in order to listen to it.
[04:02] called Whisper in order to listen to it. Then I have the Quiet and Three 1.7B
[04:04] Then I have the Quiet and Three 1.7B model. It's a large language model,
[04:06] model. It's a large language model, which is an LLM, to be able to interpret
[04:07] which is an LLM, to be able to interpret it and then come out with a response.
[04:09] it and then come out with a response. And then the Piper model, which is a
[04:11] And then the Piper model, which is a tiny text-to-speech model, is able to
[04:13] tiny text-to-speech model, is able to actually answer it out loud on the
[04:14] actually answer it out loud on the speakers. Isn't that crazy? I'm able to
[04:17] speakers. Isn't that crazy? I'm able to have full conversations with my Pi by
[04:19] have full conversations with my Pi by chaining together three different AI
[04:21] chaining together three different AI models, all on this tiny little device.
[04:24] models, all on this tiny little device. But wait, that's not all. I can also
[04:26] But wait, that's not all. I can also connect a webcam that grabs a frame,
[04:28] connect a webcam that grabs a frame, takes a picture, and I can have a tiny
[04:30] takes a picture, and I can have a tiny visual language model called Moondream
[04:32] visual language model called Moondream describe it. And the tiny text-to-speech
[04:34] describe it. And the tiny text-to-speech model Piper is able to describe what it
[04:36] model Piper is able to describe what it sees.
[04:37] sees. >> Here is the camera, the webcam,
[04:40] >> Here is the camera, the webcam, attached to the Raspberry Pi.
[04:42] attached to the Raspberry Pi. >> The image features a woman sitting in a
[04:44] >> The image features a woman sitting in a chair looking at her cell phone. She is
[04:46] chair looking at her cell phone. She is wearing a black shirt and is surrounded
[04:49] wearing a black shirt and is surrounded by a variety of books and other items.
[04:51] by a variety of books and other items. There are at least 13 books scattered
[04:53] There are at least 13 books scattered around the room, some of which are
[04:55] around the room, some of which are placed on a bookshelf. A backpack can be
[04:57] placed on a bookshelf. A backpack can be seen near the woman. A potted plant is
[04:59] seen near the woman. A potted plant is located close to her. The scene suggests
[05:02] located close to her. The scene suggests that the woman might be engaged in
[05:03] that the woman might be engaged in reading or studying, as she is
[05:05] reading or studying, as she is surrounded by numerous books and other
[05:07] surrounded by numerous books and other items.
[05:08] items. >> So yeah, you can pretty much run
[05:09] >> So yeah, you can pretty much run micro-to-small large language models
[05:11] micro-to-small large language models very easily on the Raspberry Pi, as well
[05:13] very easily on the Raspberry Pi, as well as the tiny tier visual language models,
[05:15] as the tiny tier visual language models, tiny text-to-speech models, and small
[05:17] tiny text-to-speech models, and small but decent speech-to-text models. It
[05:19] but decent speech-to-text models. It does struggle to run mid-size large
[05:21] does struggle to run mid-size large language models, but if you really want
[05:22] language models, but if you really want to, you kind of can do it. And it can
[05:25] to, you kind of can do it. And it can kind of barely run small code tier
[05:27] kind of barely run small code tier models as well. But it really cannot do
[05:29] models as well. But it really cannot do image generation, music generation, or
[05:31] image generation, music generation, or video generation. Not actually because a
[05:32] video generation. Not actually because a small image generation model wouldn't
[05:34] small image generation model wouldn't fit on here. It does. The problem is
[05:36] fit on here. It does. The problem is that it doesn't have any GPUs, so it's
[05:38] that it doesn't have any GPUs, so it's just like painfully slow to do that. And
[05:40] just like painfully slow to do that. And I will explain GPUs a little bit later.
[05:42] I will explain GPUs a little bit later. But it does make up for it because you
[05:44] But it does make up for it because you can build using the Raspberry Pi. You
[05:46] can build using the Raspberry Pi. You can add so many different types of
[05:48] can add so many different types of accessories and sensors to your
[05:50] accessories and sensors to your Raspberry Pi. In fact, I believe the
[05:51] Raspberry Pi. In fact, I believe the Hugging Face robots are running off a
[05:53] Hugging Face robots are running off a Raspberry Pi as well. So, yes, I'm going
[05:55] Raspberry Pi as well. So, yes, I'm going to put on a summary slide now, including
[05:57] to put on a summary slide now, including some ideas of things that you can build
[05:59] some ideas of things that you can build with a Raspberry Pi. And please do check
[06:00] with a Raspberry Pi. And please do check out the free guide linked below for a
[06:02] out the free guide linked below for a quick start guide. Now, let's talk about
[06:03] quick start guide. Now, let's talk about the iPhone 16, which also has 8 gigs of
[06:06] the iPhone 16, which also has 8 gigs of RAM, [music] same as the Raspberry Pi,
[06:08] RAM, [music] same as the Raspberry Pi, but it is so different. For one, because
[06:10] but it is so different. For one, because it is running on iOS, Apple does limit
[06:13] it is running on iOS, Apple does limit each app to only be able to use around 4
[06:15] each app to only be able to use around 4 or 5 gigs of RAM. So, even though it
[06:17] or 5 gigs of RAM. So, even though it technically has 8 gigs of RAM, you
[06:18] technically has 8 gigs of RAM, you actually aren't able to run the mid-size
[06:20] actually aren't able to run the mid-size level of models from 7 to 14 B that you
[06:23] level of models from 7 to 14 B that you can't do using the Raspberry Pi, because
[06:24] can't do using the Raspberry Pi, because like Apple just doesn't let you do it,
[06:26] like Apple just doesn't let you do it, unfortunately. Also, because of Apple
[06:27] unfortunately. Also, because of Apple reasons, you can't just be like putting
[06:29] reasons, you can't just be like putting on things that you wish onto your
[06:31] on things that you wish onto your iPhone. You have to do it through
[06:32] iPhone. You have to do it through Apple's official system, in which you
[06:34] Apple's official system, in which you need to install an app, and the app
[06:36] need to install an app, and the app allows you to download, install, and run
[06:38] allows you to download, install, and run your local AI models. To get the Gemma 4
[06:40] your local AI models. To get the Gemma 4 model, you need to download the AI Edge
[06:42] model, you need to download the AI Edge Gallery from Google, and then download
[06:44] Gallery from Google, and then download the models locally on your phone. This
[06:45] the models locally on your phone. This phone is able to run the small class
[06:47] phone is able to run the small class visual language models, meaning it can
[06:49] visual language models, meaning it can analyze images of the 1 to 4 B range
[06:51] analyze images of the 1 to 4 B range very comfortably, since it's only 1.5
[06:53] very comfortably, since it's only 1.5 gigs. For the image generation, you need
[06:55] gigs. For the image generation, you need to download an app called Draw Things,
[06:56] to download an app called Draw Things, and you can download and run any small
[06:59] and you can download and run any small image generation models at around the 1
[07:01] image generation models at around the 1 B range with no problem. The Stable
[07:03] B range with no problem. The Stable Diffusion 1.5, for example, is 2 gigs.
[07:05] Diffusion 1.5, for example, is 2 gigs. You can run it very comfortably. You can
[07:06] You can run it very comfortably. You can also run medium and large speech text
[07:08] also run medium and large speech text models like the Whisper Large very
[07:10] models like the Whisper Large very comfortably, and all text-to-speech
[07:12] comfortably, and all text-to-speech models, too. And finally, you can run a
[07:14] models, too. And finally, you can run a model called detection model. It's
[07:16] model called detection model. It's actually very cool. People don't really
[07:17] actually very cool. People don't really talk about it very much for some reason.
[07:19] talk about it very much for some reason. You can download an app called
[07:20] You can download an app called Ultralytics, and download and run
[07:21] Ultralytics, and download and run [music] the YOLO 11 N model. The YOLO 11
[07:24] [music] the YOLO 11 N model. The YOLO 11 N model allows you to do object
[07:26] N model allows you to do object recognition to understand the scene, and
[07:27] recognition to understand the scene, and it's the underlying technology behind
[07:29] it's the underlying technology behind all things from facial recognition on
[07:31] all things from facial recognition on your devices to self-driving cars, cuz
[07:33] your devices to self-driving cars, cuz you know, you got to be able to
[07:35] you know, you got to be able to recognize different objects as we're
[07:36] recognize different objects as we're driving. We don't really talk about this
[07:38] driving. We don't really talk about this class of models very much, these
[07:39] class of models very much, these detection models, but they're actually
[07:41] detection models, but they're actually very, very useful. Isn't that really
[07:42] very, very useful. Isn't that really cool? I'm going to put on screen now a
[07:44] cool? I'm going to put on screen now a summary slide including some ideas of
[07:46] summary slide including some ideas of things that you can build using your
[07:48] things that you can build using your phone with local AI.
[07:54] A small lesson on AI hardware. Now, think about a device, any device.
[07:57] think about a device, any device. It is like a restaurant kitchen.
[07:59] It is like a restaurant kitchen. Downstairs, we have a walk-in freezer
[08:01] Downstairs, we have a walk-in freezer and a storage space. This is where we
[08:02] and a storage space. This is where we store all the ingredients, all of the
[08:04] store all the ingredients, all of the things. Then we have the prep counter.
[08:05] things. Then we have the prep counter. This is where we load up all the
[08:06] This is where we load up all the ingredients that we need right now for
[08:08] ingredients that we need right now for the dish that we want to make. Now,
[08:09] the dish that we want to make. Now, let's talk about people who work in the
[08:10] let's talk about people who work in the kitchen. We have the head chef. The head
[08:12] kitchen. We have the head chef. The head chef is very advanced. They can make any
[08:14] chef is very advanced. They can make any sort of dish, but just one head chef.
[08:16] sort of dish, but just one head chef. There is also a brigade of line cooks.
[08:18] There is also a brigade of line cooks. These line cooks are less experienced,
[08:20] These line cooks are less experienced, less versatile, but we have a lot of
[08:21] less versatile, but we have a lot of them that can help us out. And finally,
[08:23] them that can help us out. And finally, we have specialized machines bolted to
[08:25] we have specialized machines bolted to the walls like say an onion machine that
[08:27] the walls like say an onion machine that only chops onions. Or like a noodle
[08:29] only chops onions. Or like a noodle slicing machine that just automatically
[08:31] slicing machine that just automatically sizes noodles. I don't know if you guys
[08:32] sizes noodles. I don't know if you guys have seen those before, [music] but
[08:33] have seen those before, [music] but basically these machines can only do one
[08:35] basically these machines can only do one thing. It does that one thing really
[08:36] thing. It does that one thing really well and really fast and it uses almost
[08:38] well and really fast and it uses almost no electricity. Now, between the prep
[08:40] no electricity. Now, between the prep counter and the chefs and the cooks and
[08:41] counter and the chefs and the cooks and the machines, there is a conveyor belt
[08:44] the machines, there is a conveyor belt passageway. This is how we get the
[08:45] passageway. This is how we get the ingredients from the prep counter to the
[08:47] ingredients from the prep counter to the chefs, cooks, and machines to process
[08:48] chefs, cooks, and machines to process them into hopefully a meal. So, say for
[08:50] them into hopefully a meal. So, say for example, we want to prepare a salad.
[08:52] example, we want to prepare a salad. Well, first got to go get all of the
[08:54] Well, first got to go get all of the salad stuff from a deep storage in the
[08:56] salad stuff from a deep storage in the freezer and put them onto prep counter
[08:57] freezer and put them onto prep counter like your carrots, lettuce, olives,
[08:59] like your carrots, lettuce, olives, [music] chicken, other salad stuff. Then
[09:01] [music] chicken, other salad stuff. Then we put on the conveyor belt and it gets
[09:03] we put on the conveyor belt and it gets passed through and the head chef starts
[09:04] passed through and the head chef starts giving out orders. Tells all the line
[09:06] giving out orders. Tells all the line cooks to be chopping up all the
[09:07] cooks to be chopping up all the vegetables and also starts up the onion
[09:09] vegetables and also starts up the onion machine to be chopping up onions [music]
[09:11] machine to be chopping up onions [music] while he himself is only say like mixing
[09:14] while he himself is only say like mixing the sauce because that's like the tricky
[09:16] the sauce because that's like the tricky part. And then after a few minutes,
[09:18] part. And then after a few minutes, everything comes together and voila, we
[09:20] everything comes together and voila, we get a salad. Yay! Amazing. So, this is a
[09:22] get a salad. Yay! Amazing. So, this is a great analogy for how AI models work on
[09:25] great analogy for how AI models work on our devices. So, this time what we want
[09:26] our devices. So, this time what we want to be cooking is a model. So, we walk
[09:29] to be cooking is a model. So, we walk down to our freezer downstairs except we
[09:30] down to our freezer downstairs except we call it storage and we grab our model
[09:33] call it storage and we grab our model and we put it onto our prep counter
[09:34] and we put it onto our prep counter which we call the RAM. Then we pass it
[09:36] which we call the RAM. Then we pass it along the conveyor belt which we call a
[09:38] along the conveyor belt which we call a memory bus, and hand it to our head
[09:40] memory bus, and hand it to our head chef, call it the CPU, who then also
[09:42] chef, call it the CPU, who then also directs the line cooks to start cooking
[09:44] directs the line cooks to start cooking up parts of the model. The line cooks
[09:46] up parts of the model. The line cooks are called the GPU, and also start up
[09:48] are called the GPU, and also start up the little specialized bolted machines,
[09:50] the little specialized bolted machines, the onion machine, which we call the
[09:52] the onion machine, which we call the NPU. And after all this cooking, your
[09:54] NPU. And after all this cooking, your model is able to produce something, like
[09:56] model is able to produce something, like respond to your question of, "Hi, how
[09:58] respond to your question of, "Hi, how are you?" The model then can say,
[10:00] are you?" The model then can say, "Hello, I am good. How are you?" Okay,
[10:02] "Hello, I am good. How are you?" Okay, make sense? So, every time we want to be
[10:03] make sense? So, every time we want to be working with the model, we need to be
[10:05] working with the model, we need to be going through this entire process of
[10:07] going through this entire process of cooking. Great. Now you understand the
[10:08] cooking. Great. Now you understand the major components of hardware when it
[10:10] major components of hardware when it comes to AI models. However, remember
[10:12] comes to AI models. However, remember the question that we asked earlier? Why
[10:13] the question that we asked earlier? Why is it that a Raspberry Pi has 8 gigs of
[10:15] is it that a Raspberry Pi has 8 gigs of RAM and an iPhone has 8 gigs of RAMs,
[10:18] RAM and an iPhone has 8 gigs of RAMs, too, but they are so different? Models
[10:20] too, but they are so different? Models run on iPhone are much faster, and it's
[10:23] run on iPhone are much faster, and it's able to do image generation, while the
[10:24] able to do image generation, while the Raspberry Pi cannot. Well, that is
[10:26] Raspberry Pi cannot. Well, that is [music] because these two devices have
[10:28] [music] because these two devices have the same amount of RAM, which means that
[10:29] the same amount of RAM, which means that the same amount of capacity, but they do
[10:31] the same amount of capacity, but they do not have the same amount of bandwidth,
[10:34] not have the same amount of bandwidth, which is referring to the conveyor belt
[10:36] which is referring to the conveyor belt between the prep counter [music]
[10:38] between the prep counter [music] and our cook and our chefs. You see, for
[10:40] and our cook and our chefs. You see, for most large language models, they're
[10:41] most large language models, they're bottlenecked by how quickly you can
[10:43] bottlenecked by how quickly you can deliver them from the RAM, the prep
[10:45] deliver them from the RAM, the prep counter, to the chefs and the cooks to
[10:47] counter, to the chefs and the cooks to and the machines to process the model
[10:49] and the machines to process the model and get them to be running. On a
[10:50] and get them to be running. On a Raspberry Pi, this conveyor belt, the
[10:52] Raspberry Pi, this conveyor belt, the memory bus, is quite narrow and slow.
[10:54] memory bus, is quite narrow and slow. So, it physically takes longer to be
[10:56] So, it physically takes longer to be able to be processed. And on top of
[10:58] able to be processed. And on top of that, a Raspberry Pi only has a CPU
[11:01] that, a Raspberry Pi only has a CPU without any GPUs or NPUs. So, it's
[11:03] without any GPUs or NPUs. So, it's basically like having a single head
[11:05] basically like having a single head chef, very capable, but only a single
[11:07] chef, very capable, but only a single pair of hands having to do everything to
[11:09] pair of hands having to do everything to run this model. That's why it is really,
[11:10] run this model. That's why it is really, really slow. While for the iPhone, it
[11:12] really slow. While for the iPhone, it has CPUs, GPUs, and NPUs. That's why
[11:14] has CPUs, GPUs, and NPUs. That's why it's able to process things so much
[11:16] it's able to process things so much faster. So, that explains why it is that
[11:18] faster. So, that explains why it is that things run so slowly on the Pi, but run
[11:19] things run so slowly on the Pi, but run so quickly on iPhone. But, what about
[11:21] so quickly on iPhone. But, what about image generation? The Pi simply cannot
[11:23] image generation? The Pi simply cannot do image generation, and that again is
[11:25] do image generation, and that again is because of the lack of GPUs. You see,
[11:27] because of the lack of GPUs. You see, when it comes to image, video, and music
[11:28] when it comes to image, video, and music generation, [music] it is really
[11:30] generation, [music] it is really processing heavy. So, if you just only
[11:31] processing heavy. So, if you just only have CPUs, no matter how hard they work,
[11:34] have CPUs, no matter how hard they work, it's just not enough to be able to
[11:35] it's just not enough to be able to generate music, images, and videos. So,
[11:37] generate music, images, and videos. So, you really got to have some GPUs, like
[11:40] you really got to have some GPUs, like the iPhone, to be able to do that. We
[11:41] the iPhone, to be able to do that. We will return to this analogy a little bit
[11:43] will return to this analogy a little bit later as I explain more devices. But,
[11:45] later as I explain more devices. But, for now, amazing. You now have an
[11:47] for now, amazing. You now have an understanding of AI hardware. Yay! I'll
[11:50] understanding of AI hardware. Yay! I'll put on screen now a little pop quiz.
[11:52] put on screen now a little pop quiz. Answer these questions and put them into
[11:54] Answer these questions and put them into the comments to make sure that you're
[11:55] the comments to make sure that you're paying attention. Of course, what I said
[11:57] paying attention. Of course, what I said about AI hardware is much more
[11:58] about AI hardware is much more simplified than it actually is. There's
[12:00] simplified than it actually is. There's concepts like VRAM, unified memory, like
[12:03] concepts like VRAM, unified memory, like so much more, which I'm not going to go
[12:04] so much more, which I'm not going to go into too much more detail about in this
[12:06] into too much more detail about in this video, cuz I'm sure this video is
[12:07] video, cuz I'm sure this video is already very long. But, this is like the
[12:09] already very long. But, this is like the general introduction that will help you
[12:10] general introduction that will help you a lot in figuring out what kind of
[12:12] a lot in figuring out what kind of models can run on what kind of devices.
[12:14] models can run on what kind of devices. So, as you guys can see from this video,
[12:16] So, as you guys can see from this video, I have been a very into tinkering and
[12:18] I have been a very into tinkering and running open-source models. And the next
[12:20] running open-source models. And the next obvious step is also tinkering and
[12:22] obvious step is also tinkering and customizing the open-source models
[12:23] customizing the open-source models themselves. For that, Crusoe
[12:25] themselves. For that, Crusoe Intelligence Foundry has been amazing.
[12:27] Intelligence Foundry has been amazing. It primarily gives you two things:
[12:28] It primarily gives you two things: serverless inference to run open models
[12:31] serverless inference to run open models without touching any of the underlying
[12:32] without touching any of the underlying GPU infra. And serverless fine-tuning to
[12:35] GPU infra. And serverless fine-tuning to customize the open models on your own
[12:37] customize the open models on your own data without having to own or manage any
[12:39] data without having to own or manage any hardware. You can fine-tune a model,
[12:40] hardware. You can fine-tune a model, deploy it in one click, and start
[12:42] deploy it in one click, and start calling it with an API in minutes.
[12:44] calling it with an API in minutes. Seriously, the first time that I did
[12:45] Seriously, the first time that I did this, I almost shed a tear. There is no
[12:47] this, I almost shed a tear. There is no cluster supervision or crazy long
[12:49] cluster supervision or crazy long setups. I cannot even explain how
[12:51] setups. I cannot even explain how painful this used to be. So, for today,
[12:53] painful this used to be. So, for today, anybody that's building with open models
[12:55] anybody that's building with open models who don't want the infrastructure
[12:56] who don't want the infrastructure overhead to eat into actual build time.
[12:58] overhead to eat into actual build time. This is a really clean and easy path to
[13:00] This is a really clean and easy path to get started. And now, when you sign up,
[13:01] get started. And now, when you sign up, you will get $5 of free credit. You can
[13:04] you will get $5 of free credit. You can now try out Crusoe, link is in the
[13:05] now try out Crusoe, link is in the description. Thank you so much, Crusoe,
[13:06] description. Thank you so much, Crusoe, for sponsoring this portion of the
[13:07] for sponsoring this portion of the video. Now, back to the video. Okay, now
[13:09] video. Now, back to the video. Okay, now let's move on to the next category of
[13:11] let's move on to the next category of devices, which is personal computers,
[13:14] devices, which is personal computers, such as my MacBook Pro that I'm using
[13:16] such as my MacBook Pro that I'm using right now.
[13:22] So, my MacBook Pro is 32 gigs, but of course, there are other machines in this
[13:24] course, there are other machines in this category as well, like my older machine,
[13:26] category as well, like my older machine, which is a MacBook Air, and of course
[13:28] which is a MacBook Air, and of course Windows laptops and Linux laptops, too.
[13:30] Windows laptops and Linux laptops, too. They all belong these portable personal
[13:32] They all belong these portable personal computer personal machines category. So,
[13:34] computer personal machines category. So, the reason why I got a MacBook Pro with
[13:36] the reason why I got a MacBook Pro with 32 gigs of RAM is because this is the
[13:38] 32 gigs of RAM is because this is the machine that pretty much allows me to
[13:41] machine that pretty much allows me to run any category of AI models. I can run
[13:44] run any category of AI models. I can run large language models, coding models,
[13:46] large language models, coding models, visual language models for visual
[13:48] visual language models for visual analysis, image generation, video
[13:50] analysis, image generation, video generation, text-to-speech,
[13:51] generation, text-to-speech, speech-to-text, audio generation, voice
[13:53] speech-to-text, audio generation, voice cloning, and music generation.
[14:03] >> All of this I can run locally. And not only can I run each of these models
[14:04] only can I run each of these models locally by itself, I'm also able to use
[14:07] locally by itself, I'm also able to use these models in different ways by using
[14:09] these models in different ways by using it with different types software. For
[14:10] it with different types software. For example, with my Hermes agent, which I
[14:12] example, with my Hermes agent, which I use to run many aspects of my life and
[14:15] use to run many aspects of my life and my work, I can run pretty much any
[14:16] my work, I can run pretty much any mid-size to large-size local model, like
[14:19] mid-size to large-size local model, like the Qwen 3 14B, 16B, 32B, some of my
[14:22] the Qwen 3 14B, 16B, 32B, some of my go-tos in the Qwen family. And I can run
[14:24] go-tos in the Qwen family. And I can run the Qwen 3 Coder 30B locally also an
[14:27] the Qwen 3 Coder 30B locally also an open-source coding harness like Open
[14:28] open-source coding harness like Open Code, and it works pretty good. My
[14:30] Code, and it works pretty good. My favorite for image generation is Flux
[14:32] favorite for image generation is Flux Dev. I'm going to put a summary sign now
[14:34] Dev. I'm going to put a summary sign now of all the different types of models
[14:35] of all the different types of models that you can run in this personal
[14:36] that you can run in this personal computer personal machine category, as
[14:38] computer personal machine category, as well as some ideas of things that you
[14:39] well as some ideas of things that you can build with these models. Now, I know
[14:41] can build with these models. Now, I know what you're thinking already, "But Tina,
[14:42] what you're thinking already, "But Tina, I don't have a 32 gig MacBook Pro."
[14:45] I don't have a 32 gig MacBook Pro." Understandable. It is really expensive.
[14:47] Understandable. It is really expensive. I only got this machine because it is
[14:48] I only got this machine because it is literally my job to be testing out
[14:50] literally my job to be testing out models and things, right? Don't worry, I
[14:51] models and things, right? Don't worry, I got you. I'm also going to put on screen
[14:53] got you. I'm also going to put on screen now the models that you can run if you
[14:54] now the models that you can run if you have 8 gigs of RAM and 16 gigs of RAM.
[14:57] have 8 gigs of RAM and 16 gigs of RAM. These are the general RAM sizes of
[14:58] These are the general RAM sizes of laptops that most people have. But, if
[15:00] laptops that most people have. But, if you do have something that's not like 8
[15:02] you do have something that's not like 8 gigs or 16 gigs, literally you have
[15:04] gigs or 16 gigs, literally you have something smaller, bigger, something in
[15:05] something smaller, bigger, something in the middle, that is okay as well.
[15:06] the middle, that is okay as well. Because I'm also teach you a formula for
[15:09] Because I'm also teach you a formula for calculating roughly the size of model
[15:11] calculating roughly the size of model that you can run on your machine giving
[15:12] that you can run on your machine giving the amount of RAM that you have. Okay,
[15:14] the amount of RAM that you have. Okay, ready? The equation is that take the
[15:15] ready? The equation is that take the total amount of RAM that your machine
[15:17] total amount of RAM that your machine says it has, subtract that by 25% of it,
[15:21] says it has, subtract that by 25% of it, because this is used up by like other
[15:22] because this is used up by like other stuff. And the rest is the actual usable
[15:24] stuff. And the rest is the actual usable amount of RAM that you have. Divided by
[15:26] amount of RAM that you have. Divided by 0.6 and that equals the amount of
[15:28] 0.6 and that equals the amount of parameters that your model can have. For
[15:30] parameters that your model can have. For example, my MacBook Pro says it has 32
[15:33] example, my MacBook Pro says it has 32 gigs of RAM. So I subtract 25% of that,
[15:35] gigs of RAM. So I subtract 25% of that, which means I have 24 gigs of usable
[15:37] which means I have 24 gigs of usable RAM. Now I do 24 divided by 0.6 to get
[15:40] RAM. Now I do 24 divided by 0.6 to get 40. So my MacBook Pro can fit a model of
[15:42] 40. So my MacBook Pro can fit a model of up to 40 billion parameters. That is a
[15:44] up to 40 billion parameters. That is a very rough way of figuring it out. Of
[15:46] very rough way of figuring it out. Of course, you can also just ask one of
[15:48] course, you can also just ask one of your favorite AI chatbots. Hey, this is
[15:51] your favorite AI chatbots. Hey, this is what kind of models can I fit on it? You
[15:53] what kind of models can I fit on it? You know, that works too. But in any case, I
[15:55] know, that works too. But in any case, I hope that is helpful. I want to now move
[15:56] hope that is helpful. I want to now move on to the next category of devices, home
[16:00] on to the next category of devices, home servers. The two that I have to demo
[16:01] servers. The two that I have to demo right now is the Mac Studio and the AMD
[16:04] right now is the Mac Studio and the AMD Ryzen AI Halo.
[16:10] All right, the Mac Studio and the AMD Ryzen. These are examples of the home
[16:12] Ryzen. These are examples of the home server class. There are a lot of other
[16:14] server class. There are a lot of other machines that fit into this category. I
[16:16] machines that fit into this category. I would say the cheapest entry-level here
[16:18] would say the cheapest entry-level here would be a Mac Mini. Although those are
[16:20] would be a Mac Mini. Although those are really hard to get these days. I
[16:21] really hard to get these days. I actually only got the Mac Studio because
[16:23] actually only got the Mac Studio because I couldn't get a Mac Mini. Anyways, at
[16:24] I couldn't get a Mac Mini. Anyways, at this tier, what is the most attractive
[16:26] this tier, what is the most attractive and why you would get something like
[16:27] and why you would get something like this is for two reasons. The first one
[16:29] this is for two reasons. The first one is that it is a dedicated always-on
[16:31] is that it is a dedicated always-on machine. So unlike your laptop, which
[16:33] machine. So unlike your laptop, which you got to carry around and close and
[16:34] you got to carry around and close and stuff like that. And when you close it,
[16:36] stuff like that. And when you close it, your, you know, your model stop working
[16:37] your, you know, your model stop working in case you were doing something with
[16:38] in case you were doing something with it. But the home servers, these machines
[16:40] it. But the home servers, these machines are always-on. They are designed to be
[16:42] are always-on. They are designed to be always-on. So they don't close down. You
[16:44] always-on. So they don't close down. You can constantly doing stuff and running
[16:45] can constantly doing stuff and running your AI models 24/7. That's the first
[16:47] your AI models 24/7. That's the first attractive part. And the second reason
[16:48] attractive part. And the second reason is that generally these home server
[16:50] is that generally these home server devices do have more capacity and
[16:52] devices do have more capacity and bandwidth. So it can run a bigger models
[16:55] bandwidth. So it can run a bigger models and do it faster. Let's first talk about
[16:56] and do it faster. Let's first talk about the Mac Studio here. It has 64 gigs of
[16:58] the Mac Studio here. It has 64 gigs of RAM. Pop quiz. It says it has 64 gigs of
[17:01] RAM. Pop quiz. It says it has 64 gigs of RAM. How much of it is actually usable?
[17:03] RAM. How much of it is actually usable? And what is the largest model in
[17:05] And what is the largest model in billions of parameters that can fit on
[17:07] billions of parameters that can fit on my Mac Studio? Were you paying
[17:08] my Mac Studio? Were you paying attention? Put it into the comments.
[17:09] attention? Put it into the comments. Amazing. Hope you got that. My Mac
[17:11] Amazing. Hope you got that. My Mac Studio is where I like to run my local
[17:13] Studio is where I like to run my local models to use for my local AI agents and
[17:16] models to use for my local AI agents and also allow other devices. Remember this
[17:18] also allow other devices. Remember this device, the Arduino Uno R4? That
[17:22] device, the Arduino Uno R4? That couldn't run anything by itself. I also
[17:23] couldn't run anything by itself. I also like to be able to connect this with my
[17:25] like to be able to connect this with my Mac Studio, so I can use the models that
[17:27] Mac Studio, so I can use the models that are being run on my Mac Studio. This
[17:29] are being run on my Mac Studio. This Arduino Uno is using the Qwen 3.6 35B
[17:34] Arduino Uno is using the Qwen 3.6 35B model on this Mac Studio in order to
[17:36] model on this Mac Studio in order to display encouraging happy messages.
[17:39] display encouraging happy messages. Write into the comments
[17:41] Write into the comments what this says if you can read it. Yay!
[17:44] what this says if you can read it. Yay! That's really cool, right? Really with
[17:45] That's really cool, right? Really with this Mac Studio and all devices that are
[17:46] this Mac Studio and all devices that are bigger and more powerful than this, it's
[17:48] bigger and more powerful than this, it's not about unlocking new categories of AI
[17:50] not about unlocking new categories of AI models at this point. It's just about
[17:51] models at this point. It's just about being able to run a bigger models,
[17:53] being able to run a bigger models, higher quality things to get higher
[17:54] higher quality things to get higher quality responses, and faster. In the
[17:56] quality responses, and faster. In the case of the Mac Studio, I can run large
[17:59] case of the Mac Studio, I can run large tier large language models between a 27
[18:01] tier large language models between a 27 and 32 billion parameters, as well as
[18:03] and 32 billion parameters, as well as large code models, large image models,
[18:06] large code models, large image models, and large music generation models.
[18:08] and large music generation models. >> [music]
[18:17] >> For video generation, I can now run mid-tier video generation, like the One
[18:20] mid-tier video generation, like the One 2.2, but it is slow. It is really slow
[18:23] 2.2, but it is slow. It is really slow still. I'm going to put a summary slide
[18:25] still. I'm going to put a summary slide now with all the models that you can run
[18:26] now with all the models that you can run with a Mac Studio, as well as some ideas
[18:28] with a Mac Studio, as well as some ideas for things we can build. And let's move
[18:30] for things we can build. And let's move on to the AMD Halo, which is 128 GB of
[18:33] on to the AMD Halo, which is 128 GB of advertised RAM. Now, with 128 GB of
[18:36] advertised RAM. Now, with 128 GB of advertised RAM, around 96 GB of usable
[18:39] advertised RAM, around 96 GB of usable RAM, it is now able to comfortably run
[18:41] RAM, it is now able to comfortably run extra large models in the 70B range and
[18:45] extra large models in the 70B range and frontier models in the 100 to 250B
[18:47] frontier models in the 100 to 250B range. We can see that Llama 3.3 70B is
[18:50] range. We can see that Llama 3.3 70B is able to run fine, and GPT-OSS 120B is
[18:53] able to run fine, and GPT-OSS 120B is also able to run fine. It's also able to
[18:55] also able to run fine. It's also able to run extra large tier of coding models,
[18:57] run extra large tier of coding models, like the Deep Seek Coder V2. Great. So,
[19:00] like the Deep Seek Coder V2. Great. So, we can see that it can run bigger models
[19:02] we can see that it can run bigger models now. Makes sense. However, what I find
[19:04] now. Makes sense. However, what I find the most useful of having something like
[19:06] the most useful of having something like this is the ability of having a lot of
[19:08] this is the ability of having a lot of different models loaded simultaneously
[19:10] different models loaded simultaneously and working simultaneously because it
[19:12] and working simultaneously because it has that massive amount of memory,
[19:13] has that massive amount of memory, right? So, I could be using a coding
[19:14] right? So, I could be using a coding agent, the large language models, and
[19:16] agent, the large language models, and doing like image video generation all at
[19:18] doing like image video generation all at the same time. I'm going to put on
[19:19] the same time. I'm going to put on screen now all the models that you can
[19:20] screen now all the models that you can run with a device like the AMD Halo and
[19:23] run with a device like the AMD Halo and ideas of what you can build. But, I do
[19:24] ideas of what you can build. But, I do want to make a caveat here though. This
[19:26] want to make a caveat here though. This machine, even though it has very large
[19:28] machine, even though it has very large capacity, it actually has pretty small
[19:30] capacity, it actually has pretty small bandwidth, which means that it is slow,
[19:32] bandwidth, which means that it is slow, especially when it comes to image,
[19:34] especially when it comes to image, video, and music generation. It can do
[19:36] video, and music generation. It can do it. It's just going to do it really,
[19:38] it. It's just going to do it really, [music] really slow. Which is why I want
[19:39] [music] really slow. Which is why I want to introduce you to this final category
[19:41] to introduce you to this final category that we're going to cover today, which
[19:42] that we're going to cover today, which is GPUs.
[19:48] First, let me explain GPUs a little bit more. Remember that analogy that we had
[19:50] more. Remember that analogy that we had earlier, the restaurant kitchen analogy?
[19:52] earlier, the restaurant kitchen analogy? We said that a GPU is like having a
[19:53] We said that a GPU is like having a brigade of line cooks. Because we have
[19:55] brigade of line cooks. Because we have so many of them, they're able to work
[19:57] so many of them, they're able to work really, really quickly and they do
[19:58] really, really quickly and they do compute very fast. Now, this matters the
[20:00] compute very fast. Now, this matters the most when it comes to music generation,
[20:02] most when it comes to music generation, image generation, and video generation.
[20:04] image generation, and video generation. Cuz to be able to produce these, you
[20:05] Cuz to be able to produce these, you just need like a lot of processing
[20:07] just need like a lot of processing power. So, you need a lot of line cooks
[20:08] power. So, you need a lot of line cooks in the kitchen. The bad news is that all
[20:10] in the kitchen. The bad news is that all the devices that I went through earlier,
[20:12] the devices that I went through earlier, they do of course have GPUs, which is
[20:13] they do of course have GPUs, which is why they can do things like music
[20:15] why they can do things like music generation, image generation, and video
[20:16] generation, image generation, and video generation, but they do it really,
[20:18] generation, but they do it really, really slowly cuz they're not
[20:19] really slowly cuz they're not specialized at doing this. But, the good
[20:21] specialized at doing this. But, the good news is that there is a way to be really
[20:24] news is that there is a way to be really good at processing and be able to do
[20:26] good at processing and be able to do really fast and really good image,
[20:28] really fast and really good image, music, and video generation. And that is
[20:30] music, and video generation. And that is by getting more discrete GPUs. You see,
[20:32] by getting more discrete GPUs. You see, a GPU actually isn't just line cooks.
[20:35] a GPU actually isn't just line cooks. It's actually a bundle. When you get
[20:37] It's actually a bundle. When you get another GPU, you get cooks, but they
[20:39] another GPU, you get cooks, but they also come with their own private prep
[20:41] also come with their own private prep counters and a very wide conveyor belt,
[20:43] counters and a very wide conveyor belt, the memory pass. So, when you get more
[20:45] the memory pass. So, when you get more GPUs, you get more cooks who have their
[20:47] GPUs, you get more cooks who have their own private counter and their very own
[20:49] own private counter and their very own very wide conveyor belt, the memory
[20:51] very wide conveyor belt, the memory pass. So, they're able to get the
[20:52] pass. So, they're able to get the ingredients really fast. It's basically
[20:53] ingredients really fast. It's basically like a boost for the line cooks. So,
[20:55] like a boost for the line cooks. So, you're able to process things really,
[20:56] you're able to process things really, really quickly, cook your models really
[20:58] really quickly, cook your models really quickly. I hope that analogy makes
[21:00] quickly. I hope that analogy makes sense. It's getting really late.
[21:02] sense. It's getting really late. >> [laughter]
[21:02] >> [laughter] >> So, there are a few ways to get more
[21:04] >> So, there are a few ways to get more GPUs. Unfortunately, for all the devices
[21:06] GPUs. Unfortunately, for all the devices that we covered earlier, you cannot add
[21:08] that we covered earlier, you cannot add more GPUs to them. Just like they're not
[21:10] more GPUs to them. Just like they're not built that way. But, if you had a gaming
[21:12] built that way. But, if you had a gaming PC, for example, that would have a GPU.
[21:15] PC, for example, that would have a GPU. I I do not have a gaming PC, and I'm not
[21:17] I I do not have a gaming PC, and I'm not about to go buy one right now, cuz those
[21:19] about to go buy one right now, cuz those are expensive. But, if you do have one,
[21:20] are expensive. But, if you do have one, good news for you. You have a GPU, and
[21:22] good news for you. You have a GPU, and you can actually add more GPUs as well.
[21:24] you can actually add more GPUs as well. So, I'm going to cheat a little bit,
[21:25] So, I'm going to cheat a little bit, okay? Because I do want to show you what
[21:26] okay? Because I do want to show you what it's like to run these multi-modality
[21:27] it's like to run these multi-modality generation models on these specialized
[21:29] generation models on these specialized GPUs. So, I'm actually going to rent an
[21:32] GPUs. So, I'm actually going to rent an RTX 4090. This is a pretty high-end GPU
[21:35] RTX 4090. This is a pretty high-end GPU that you might have in a high-end gaming
[21:37] that you might have in a high-end gaming set. Let's do this quickly, because it's
[21:39] set. Let's do this quickly, because it's costing me by the hour. We're going to
[21:40] costing me by the hour. We're going to log in here, and then I'm going to run
[21:43] log in here, and then I'm going to run an image generation model.
[21:49] You can see that it is really, really quickly. And here is a video generation
[21:51] quickly. And here is a video generation as well.
[21:59] Really, really quick. Now, the downside of this GPU is that it only has 24 gigs
[22:01] of this GPU is that it only has 24 gigs of memory. So, you can think about it
[22:02] of memory. So, you can think about it almost like the opposite of the AMD
[22:04] almost like the opposite of the AMD device, because the AMD device has a lot
[22:06] device, because the AMD device has a lot of memory, has very big capacity, but
[22:08] of memory, has very big capacity, but low bandwidth. While the RTX 4090 has
[22:10] low bandwidth. While the RTX 4090 has smaller capacity, only 24 gigs, but much
[22:12] smaller capacity, only 24 gigs, but much larger bandwidth. So, in the end, you
[22:14] larger bandwidth. So, in the end, you end up being able to generate a lot of
[22:16] end up being able to generate a lot of these things and run these models, but
[22:17] these things and run these models, but you can't really fit very large-size
[22:19] you can't really fit very large-size models on it. All right, I'm going to
[22:21] models on it. All right, I'm going to now put a summary slide for the models
[22:23] now put a summary slide for the models that you can run on this device, [music]
[22:25] that you can run on this device, [music] and the things that you can build with
[22:26] and the things that you can build with it. And that finally leads me to the
[22:28] it. And that finally leads me to the final boss, the 8X H100 GPU.
[22:31] final boss, the 8X H100 GPU. >> [music]
[22:31] >> [music] >> Now, this is top tier, 640 gigs of RAM,
[22:35] >> Now, this is top tier, 640 gigs of RAM, massive capacity, and massive bandwidth.
[22:38] massive capacity, and massive bandwidth. Now, I really got to move fast on this
[22:39] Now, I really got to move fast on this one, because it's [music] costing me so
[22:41] one, because it's [music] costing me so much money every minute. But, for you
[22:43] much money every minute. But, for you guys, it's worth it. On here, not only
[22:45] guys, it's worth it. On here, not only can we run ultra-large tier large
[22:48] can we run ultra-large tier large language models up to 700 billion
[22:50] language models up to 700 billion parameter-plus ultra-large coding
[22:52] parameter-plus ultra-large coding models, 480 billion parameter-plus
[22:54] models, 480 billion parameter-plus visual language processing as well, and
[22:56] visual language processing as well, and all types of multi-modal generation.
[22:58] all types of multi-modal generation. Specifically, let's check out video
[22:59] Specifically, let's check out video generation. Using the Minimax H3 model,
[23:02] generation. Using the Minimax H3 model, we can see that it's able to generate
[23:03] we can see that it's able to generate minutes of video, and it does this so
[23:05] minutes of video, and it does this so quickly.
[23:22] >> This is pretty much what you can run assuming that you're not like a literal
[23:24] assuming that you're not like a literal model development company or just have
[23:26] model development company or just have like a lot of money. But, it really is
[23:29] like a lot of money. But, it really is comparable at this point to the frontier
[23:31] comparable at this point to the frontier models that you're paying for through
[23:32] models that you're paying for through cloud APIs. You see everything up to
[23:34] cloud APIs. You see everything up to this GPU is kind of just forcing you to
[23:36] this GPU is kind of just forcing you to choose between like capacity and
[23:38] choose between like capacity and bandwidth, right? Like the AMD Halo is
[23:40] bandwidth, right? Like the AMD Halo is all about big capacity but low
[23:41] all about big capacity but low bandwidth, and the RTX 4090 is all about
[23:44] bandwidth, and the RTX 4090 is all about small capacity and large bandwidth. But,
[23:45] small capacity and large bandwidth. But, this is when you get both. You get very
[23:47] this is when you get both. You get very big capacity and very big bandwidth. And
[23:49] big capacity and very big bandwidth. And now for the 8 H100 rented, I'm going to
[23:52] now for the 8 H100 rented, I'm going to put a summary slide now of the models
[23:54] put a summary slide now of the models that you can run with it and the things
[23:56] that you can run with it and the things that you can build. This is like
[23:58] that you can build. This is like aspirational class. Great. Amazing. Wow.
[24:01] aspirational class. Great. Amazing. Wow. Thank you so much for watching until the
[24:03] Thank you so much for watching until the end of this video. I hope this was
[24:04] end of this video. I hope this was insightful, interesting, helpful, and it
[24:07] insightful, interesting, helpful, and it has inspired you to want to build things
[24:09] has inspired you to want to build things with local AI as well. I'm going to put
[24:11] with local AI as well. I'm going to put on screen now a little quiz. Please
[24:13] on screen now a little quiz. Please answer these questions in the comments
[24:14] answer these questions in the comments below to help you retain all of the
[24:16] below to help you retain all of the information that we have covered today.
[24:18] information that we have covered today. Thank you so much, and I will see you
[24:20] Thank you so much, and I will see you guys in the next video or live stream.
All frames
Total: 40. Hero frames flagged with star.
frames/frame_0001.jpg(t=00:00)frames/frame_0002.jpg(t=00:17)frames/frame_0003.jpg(t=00:54)frames/frame_0004.jpg(t=01:31)frames/frame_0005.jpg(t=02:06)frames/frame_0006.jpg(t=02:52)frames/frame_0007.jpg(t=03:17)frames/frame_0008.jpg(t=03:58)frames/frame_0009.jpg(t=04:37)frames/frame_0010.jpg(t=05:08)frames/frame_0011.jpg(t=05:51)frames/frame_0012.jpg(t=07:02)frames/frame_0013.jpg(t=07:34)frames/frame_0014.jpg(t=08:11)frames/frame_0015.jpg(t=08:50)frames/frame_0016.jpg(t=09:21)frames/frame_0017.jpg(t=10:01)frames/frame_0018.jpg(t=10:34)frames/frame_0019.jpg(t=11:16)frames/frame_0020.jpg(t=11:50)frames/frame_0021.jpg(t=12:27)frames/frame_0022.jpg(t=13:05)frames/frame_0023.jpg(t=13:37)frames/frame_0024.jpg(t=14:15)frames/frame_0025.jpg(t=14:59)frames/frame_0026.jpg(t=15:44)frames/frame_0027.jpg(t=16:05)frames/frame_0028.jpg(t=16:39)frames/frame_0029.jpg(t=17:18)frames/frame_0030.jpg(t=18:30)frames/frame_0031.jpg(t=19:07)frames/frame_0032.jpg(t=19:46)frames/frame_0033.jpg(t=20:17)frames/frame_0034.jpg(t=20:51)frames/frame_0035.jpg(t=21:37)frames/frame_0036.jpg(t=22:13)frames/frame_0037.jpg(t=22:44)frames/frame_0038.jpg(t=23:24)frames/frame_0039.jpg(t=23:57)frames/frame_0040.jpg(t=24:18)